microsoft/wavlm-base

# WavLM-Base [Microsoft's WavLM](https://github.com/microsoft/unilm/tree/master/wavlm) The base model pretrained on 16kHz sampled speech audio. When using the model, make sure that your speech input …

azureFoundry/HuggingFace/microsoft-wavlm-base@1

WavLM-Base

Microsoft's WavLM

The base model pretrained on 16kHz sampled speech audio. When using the model, make sure that your speech input is also sampled at 16kHz.

Note: This model does not have a tokenizer as it was pretrained on audio alone. In order to use this model speech recognition, a tokenizer should be created and the model should be fine-tuned on labeled text data. Check out this blog for more in-detail explanation of how to fine-tune the model.

The model was pre-trained on 960h of Librispeech.

Paper: WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing

Authors: Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei

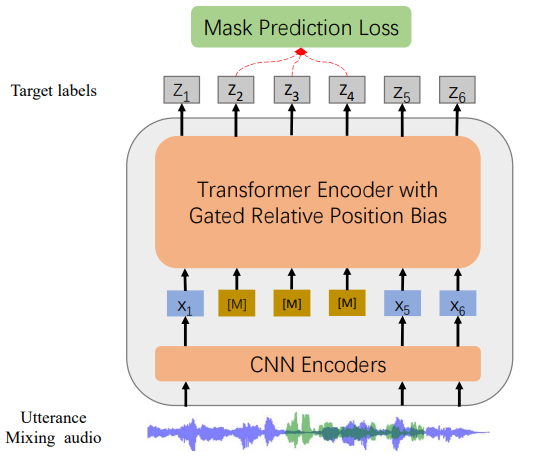
Abstract Self-supervised learning (SSL) achieves great success in speech recognition, while limited exploration has been attempted for other speech processing tasks. As speech signal contains multi-faceted information including speaker identity, paralinguistics, spoken content, etc., learning universal representations for all speech tasks is challenging. In this paper, we propose a new pre-trained model, WavLM, to solve full-stack downstream speech tasks. WavLM is built based on the HuBERT framework, with an emphasis on both spoken content modeling and speaker identity preservation. We first equip the Transformer structure with gated relative position bias to improve its capability on recognition tasks. For better speaker discrimination, we propose an utterance mixing training strategy, where additional overlapped utterances are created unsupervisely and incorporated during model training. Lastly, we scale up the training dataset from 60k hours to 94k hours. WavLM Large achieves state-of-the-art performance on the SUPERB benchmark, and brings significant improvements for various speech processing tasks on their representative benchmarks.

The original model can be found under https://github.com/microsoft/unilm/tree/master/wavlm.

Usage

This is an English pre-trained speech model that has to be fine-tuned on a downstream task like speech recognition or audio classification before it can be used in inference. The model was pre-trained in English and should therefore perform well only in English. The model has been shown to work well on the SUPERB benchmark.

Note: The model was pre-trained on phonemes rather than characters. This means that one should make sure that the input text is converted to a sequence of phonemes before fine-tuning.

Speech Recognition

To fine-tune the model for speech recognition, see the official speech recognition example.

Speech Classification

To fine-tune the model for speech classification, see the official audio classification example.

Speaker Verification

TODO

Speaker Diarization

TODO

Contribution

The model was contributed by cywang and patrickvonplaten.

License

The official license can be found here
design


microsoft/wavlm-base powered by Hugging Face Inference Toolkit

Send Request

You can use cURL or any REST Client to send a request to the AzureML endpoint with your AzureML token.

curl <AZUREML_ENDPOINT_URL> \
    -X POST \
    -H "Authorization: Bearer <AZUREML_TOKEN>" \
    -H "Content-Type: application/json" \
    -d '{"inputs":"Today is a sunny day and I will get some ice cream."}'

Supported Parameters

  • inputs (string or string[]): Either the text to create the embeddings for, or a list of texts.
  • normalize (boolean): Whether to normalize the embedding to be generated or not.
  • prompt_name (string): The name of the prompt that should be used by for encoding. If not set, no prompt will be applied. Must be a key in the sentence-transformers configuration prompts dictionary. For example if prompt_name is "query" and the prompts is {"query": "query: ", …}, then the sentence "What is the capital of France?" will be encoded as "query: What is the capital of France?" because the prompt text will be prepended before any text to encode.
  • truncate (boolean): Whether to truncate the input to match the max allowed input tokens or not.
  • truncation_direction (enum): Possible values: Left, Right.

Check the full API Specification at the Hugging Face Inference documentation.

Specifications & capabilities

Input
text
Output
embeddings
Published model ID
wavlm-base
Capabilities
embeddings

Evaluations

1–6 / 6

MTEB

57.239%

source id
mteb
leaderboard name
MTEB Pair Classification
dimension
embedding
metric
Average task score
rank
240
sample size
5
aggregation scope
splits
  • test
subsets
  • default
task_count
5
task_names
  • CREMADPairClassification
  • ESC50PairClassification
  • NMSQAPairClassification
  • VocalSoundPairClassification
  • VoxPopuliAccentPairClassification
sample_size
5
subset_count
1
subset_sample
  • default
aggregation_method
mean-of-task-means
model_revision_count
1
model_revision_sample
  • efa81aae7ff777e464159e0f877d54eac5b84f81
source model id
microsoft/wavlm-base
Original result ↗

MTEB

62.584%

source id
mteb
leaderboard name
MTEB Retrieval
dimension
embedding
metric
Average task score
rank
286
sample size
4
aggregation scope
splits
  • test
subsets
  • de
  • en
  • es
  • fr
task_count
1
task_names
  • JamAltArtistA2ARetrieval
sample_size
4
subset_count
4
subset_sample
  • de
  • en
  • es
  • fr
aggregation_method
mean-of-task-means
model_revision_count
1
model_revision_sample
  • efa81aae7ff777e464159e0f877d54eac5b84f81
source model id
microsoft/wavlm-base
Original result ↗

MTEB

48.461%

source id
mteb
leaderboard name
MTEB Reranking
dimension
embedding
metric
Average task score
rank
306
sample size
5
aggregation scope
splits
  • test
subsets
  • default
task_count
5
task_names
  • ESC50AudioReranking
  • FSDnoisy18kAudioReranking
  • GTZANAudioReranking
  • UrbanSound8KAudioReranking
  • VocalSoundAudioReranking
sample_size
5
subset_count
1
subset_sample
  • default
aggregation_method
mean-of-task-means
model_revision_count
1
model_revision_sample
  • efa81aae7ff777e464159e0f877d54eac5b84f81
source model id
microsoft/wavlm-base
Original result ↗

MTEB

42.937%

source id
mteb
leaderboard name
MTEB Other
dimension
embedding
metric
Average task score
rank
599
sample size
147
aggregation scope
splits
  • test
  • test_5s
  • train
subsets
  • afr_Latn
  • amh_Ethi
  • arb_Arab
  • asm_Beng
  • ast_Latn
  • azj_Latn
  • bel_Cyrl
  • ben_Beng
  • bos_Latn
  • bul_Cyrl
  • cat_Latn
  • ceb_Latn
  • ces_Latn
  • ckb_Arab
  • cs-CZ
  • curated
  • cym_Latn
  • dan_Latn
  • de-DE
  • default
  • deu_Latn
  • ell_Grek
  • en-GB
  • eng_Latn
  • es-ES
  • est_Latn
  • fin_Latn
  • fr-FR
  • fra_Latn
  • fuv_Latn
  • gaz_Latn
  • gle_Latn
  • glg_Latn
  • guj_Gujr
  • hau_Latn
  • heb_Hebr
  • hin_Deva
  • hrv_Latn
  • hun_Latn
  • hye_Armn
  • ibo_Latn
  • ind_Latn
  • isl_Latn
  • it-IT
  • ita_Latn
  • jav_Latn
  • jpn_Jpan
  • kam_Latn
  • kan_Knda
  • kat_Geor
  • kaz_Cyrl
  • kea_Latn
  • khk_Cyrl
  • khm_Khmr
  • kir_Cyrl
  • ko-KR
  • kor_Hang
  • lao_Laoo
  • lin_Latn
  • lit_Latn
  • ltz_Latn
  • lug_Latn
  • luo_Latn
  • lvs_Latn
  • mal_Mlym
  • mar_Deva
  • mkd_Cyrl
  • mlt_Latn
  • mri_Latn
  • mya_Mymr
  • nl-NL
  • nld_Latn
  • nob_Latn
  • noisy
  • npi_Deva
  • nso_Latn
  • nya_Latn
  • oci_Latn
  • ory_Orya
  • pan_Guru
  • pbt_Arab
  • pes_Arab
  • pl-PL
  • pol_Latn
  • por_Latn
  • pt-PT
  • ron_Latn
  • ru-RU
  • rus_Cyrl
  • slk_Latn
  • slv_Latn
  • sna_Latn
  • snd_Arab
  • som_Latn
  • spa_Latn
  • srp_Cyrl
  • swe_Latn
  • swh_Latn
  • tam_Taml
  • tel_Telu
  • tgk_Cyrl
  • tgl_Latn
  • tha_Thai
  • tur_Latn
  • ukr_Cyrl
  • umb_Latn
  • urd_Arab
  • uzn_Latn
  • vie_Latn
  • wol_Latn
  • xho_Latn
  • yor_Latn
  • zh-CN
  • zho_Hans
  • zho_Hant
  • zsm_Latn
  • zul_Latn
task_count
34
task_names
  • AmbientAcousticContext
  • AudioSetMini
  • BeijingOpera
  • BirdCLEF
  • BirdSet
  • CREMA_D
  • CommonLanguageAgeDetection
  • CommonLanguageGenderDetection
  • CommonLanguageLanguageDetection
  • ESC50
  • FSD2019Kaggle
  • FSD50K
  • FSDD
  • GTZANGenre
  • GunshotTriangulation
  • IEMOCAPEmotion
  • IEMOCAPGender
  • LibriCount
  • MInDS14
  • MridinghamStroke
  • MridinghamTonic
  • NSynth
  • SIBFLEURS
  • SpeechCommands
  • SpokeNEnglish
  • SpokenQAForIC
  • TUTAcousticScenes
  • UrbanSound8k
  • VocalSound
  • VoxCelebSA
  • VoxLingua107_Top10
  • VoxPopuliAccentID
  • VoxPopuliGenderID
  • VoxPopuliLanguageID
sample_size
147
subset_count
117
subset_sample
  • afr_Latn
  • amh_Ethi
  • arb_Arab
  • asm_Beng
  • ast_Latn
  • azj_Latn
  • bel_Cyrl
  • ben_Beng
  • bos_Latn
  • bul_Cyrl
  • cat_Latn
  • ceb_Latn
  • ces_Latn
  • ckb_Arab
  • cs-CZ
  • curated
  • cym_Latn
  • dan_Latn
  • de-DE
  • default
  • deu_Latn
  • ell_Grek
  • en-GB
  • eng_Latn
  • es-ES
  • est_Latn
  • fin_Latn
  • fr-FR
  • fra_Latn
  • fuv_Latn
aggregation_method
mean-of-task-means
model_revision_count
1
model_revision_sample
  • efa81aae7ff777e464159e0f877d54eac5b84f81
source model id
microsoft/wavlm-base
Original result ↗

MTEB

13.07%

source id
mteb
leaderboard name
MTEB Clustering
dimension
embedding
metric
Average task score
rank
653
sample size
10
aggregation scope
splits
  • test
  • train
subsets
  • default
task_count
10
task_names
  • AmbientAcousticContextClustering
  • CREMA_DClustering
  • ESC50Clustering
  • GTZANGenreClustering
  • MusicGenreClustering
  • VehicleSoundClustering
  • VoiceGenderClustering
  • VoxCelebClustering
  • VoxPopuliAccentClustering
  • VoxPopuliGenderClustering
sample_size
10
subset_count
1
subset_sample
  • default
aggregation_method
mean-of-task-means
model_revision_count
1
model_revision_sample
  • efa81aae7ff777e464159e0f877d54eac5b84f81
source model id
microsoft/wavlm-base
Original result ↗

MTEB

39.666%

source id
mteb
leaderboard name
MTEB Overall
dimension
embedding
metric
Average task score
rank
776
sample size
171
aggregation scope
splits
  • test
  • test_5s
  • train
subsets
  • afr_Latn
  • amh_Ethi
  • arb_Arab
  • asm_Beng
  • ast_Latn
  • azj_Latn
  • bel_Cyrl
  • ben_Beng
  • bos_Latn
  • bul_Cyrl
  • cat_Latn
  • ceb_Latn
  • ces_Latn
  • ckb_Arab
  • cs-CZ
  • curated
  • cym_Latn
  • dan_Latn
  • de
  • de-DE
  • default
  • deu_Latn
  • ell_Grek
  • en
  • en-GB
  • eng_Latn
  • es
  • es-ES
  • est_Latn
  • fin_Latn
  • fr
  • fr-FR
  • fra_Latn
  • fuv_Latn
  • gaz_Latn
  • gle_Latn
  • glg_Latn
  • guj_Gujr
  • hau_Latn
  • heb_Hebr
  • hin_Deva
  • hrv_Latn
  • hun_Latn
  • hye_Armn
  • ibo_Latn
  • ind_Latn
  • isl_Latn
  • it-IT
  • ita_Latn
  • jav_Latn
  • jpn_Jpan
  • kam_Latn
  • kan_Knda
  • kat_Geor
  • kaz_Cyrl
  • kea_Latn
  • khk_Cyrl
  • khm_Khmr
  • kir_Cyrl
  • ko-KR
  • kor_Hang
  • lao_Laoo
  • lin_Latn
  • lit_Latn
  • ltz_Latn
  • lug_Latn
  • luo_Latn
  • lvs_Latn
  • mal_Mlym
  • mar_Deva
  • mkd_Cyrl
  • mlt_Latn
  • mri_Latn
  • mya_Mymr
  • nl-NL
  • nld_Latn
  • nob_Latn
  • noisy
  • npi_Deva
  • nso_Latn
  • nya_Latn
  • oci_Latn
  • ory_Orya
  • pan_Guru
  • pbt_Arab
  • pes_Arab
  • pl-PL
  • pol_Latn
  • por_Latn
  • pt-PT
  • ron_Latn
  • ru-RU
  • rus_Cyrl
  • slk_Latn
  • slv_Latn
  • sna_Latn
  • snd_Arab
  • som_Latn
  • spa_Latn
  • srp_Cyrl
  • swe_Latn
  • swh_Latn
  • tam_Taml
  • tel_Telu
  • tgk_Cyrl
  • tgl_Latn
  • tha_Thai
  • tur_Latn
  • ukr_Cyrl
  • umb_Latn
  • urd_Arab
  • uzn_Latn
  • vie_Latn
  • wol_Latn
  • xho_Latn
  • yor_Latn
  • zh-CN
  • zho_Hans
  • zho_Hant
  • zsm_Latn
  • zul_Latn
task_count
55
task_names
  • AmbientAcousticContext
  • AmbientAcousticContextClustering
  • AudioSetMini
  • BeijingOpera
  • BirdCLEF
  • BirdSet
  • CREMADPairClassification
  • CREMA_D
  • CREMA_DClustering
  • CommonLanguageAgeDetection
  • CommonLanguageGenderDetection
  • CommonLanguageLanguageDetection
  • ESC50
  • ESC50AudioReranking
  • ESC50Clustering
  • ESC50PairClassification
  • FSD2019Kaggle
  • FSD50K
  • FSDD
  • FSDnoisy18kAudioReranking
  • GTZANAudioReranking
  • GTZANGenre
  • GTZANGenreClustering
  • GunshotTriangulation
  • IEMOCAPEmotion
  • IEMOCAPGender
  • JamAltArtistA2ARetrieval
  • LibriCount
  • MInDS14
  • MridinghamStroke
  • MridinghamTonic
  • MusicGenreClustering
  • NMSQAPairClassification
  • NSynth
  • SIBFLEURS
  • SpeechCommands
  • SpokeNEnglish
  • SpokenQAForIC
  • TUTAcousticScenes
  • UrbanSound8KAudioReranking
  • UrbanSound8k
  • VehicleSoundClustering
  • VocalSound
  • VocalSoundAudioReranking
  • VocalSoundPairClassification
  • VoiceGenderClustering
  • VoxCelebClustering
  • VoxCelebSA
  • VoxLingua107_Top10
  • VoxPopuliAccentClustering
  • VoxPopuliAccentID
  • VoxPopuliAccentPairClassification
  • VoxPopuliGenderClustering
  • VoxPopuliGenderID
  • VoxPopuliLanguageID
sample_size
171
subset_count
121
subset_sample
  • afr_Latn
  • amh_Ethi
  • arb_Arab
  • asm_Beng
  • ast_Latn
  • azj_Latn
  • bel_Cyrl
  • ben_Beng
  • bos_Latn
  • bul_Cyrl
  • cat_Latn
  • ceb_Latn
  • ces_Latn
  • ckb_Arab
  • cs-CZ
  • curated
  • cym_Latn
  • dan_Latn
  • de
  • de-DE
  • default
  • deu_Latn
  • ell_Grek
  • en
  • en-GB
  • eng_Latn
  • es
  • es-ES
  • est_Latn
  • fin_Latn
aggregation_method
mean-of-task-means
model_revision_count
1
model_revision_sample
  • efa81aae7ff777e464159e0f877d54eac5b84f81
source model id
microsoft/wavlm-base
Original result ↗

Provider specifications & access

1–1 / 1

microsoft/wavlm-base ↗

source model id
HuggingFace/microsoft-wavlm-base@1
hosting
foundry-managed-compute
platforms
  • Microsoft Foundry
license
unknown
architecture
input_modalities
  • text
output_modalities
  • embeddings
capabilities

    Original sources

    1–5 / 5

    Hugging Face · microsoft/wavlm-base ↗

    Microsoft Foundry · Model page ↗

    Microsoft Foundry · Model documentation ↗

    Hugging Face · Catalog ↗

    Microsoft Foundry · Catalog ↗

    Source links

    1–2 / 2

    Explore more models

    Models

    Loading
    EVIDENCE / COMPARISON

    Benchmarks

    Explore every benchmark

    Loading

    These charts contain model-linked results. The charts above also include unlinked source profiles. Compare scores within each evaluation. Model quality, usage, transparency and system performance measure different things.

    Install TensorTrace